Вход на сайт

Просмотр новости

Найдите то, что Вас интересует

Android Bench 2.0 focuses on long-horizon tasks, agent evaluations

Дата публикации: 17-09-2026 16:00:00

Google’s development of Android Bench continues today with a version 2.0 that reflects how AI can handle more complex development tasks.
more…
Основное содержимое страницы с новостью.

Google’s development of Android Bench continues today with a version 2.0 that reflects how AI can handle more complex development tasks.

The first version “focused on incremental changes to existing repositories,” like bug fixes or smaller feature requests. Android Bench 2.0 targets “tasks of great complexity that take an engineer multiple days or even a week to complete,” such as adding new features, building apps from scratch, and converting cross-platform apps to Android.

This new focus required “more nuanced evaluation and scoring” that goes beyond pass or fail grading. Google is moving from binary to continuous scoring:

We calculate this completion rate through a combination of factors like functionality, visual fidelity, and avoiding regressions. We also apply objective scoring penalties for deviations from evaluation instructions or structural constraints.

Google has rated Gemini 3.7/3.8 Flash, OpenAI GPT-6, Anthropic Fable 5.1, Kimi K3, and Qwen 3.8 Max. GPT-6 Astra is at the top of the benchmark with a 28% pass rate (compared to scores in the 90% range with the previous approach).
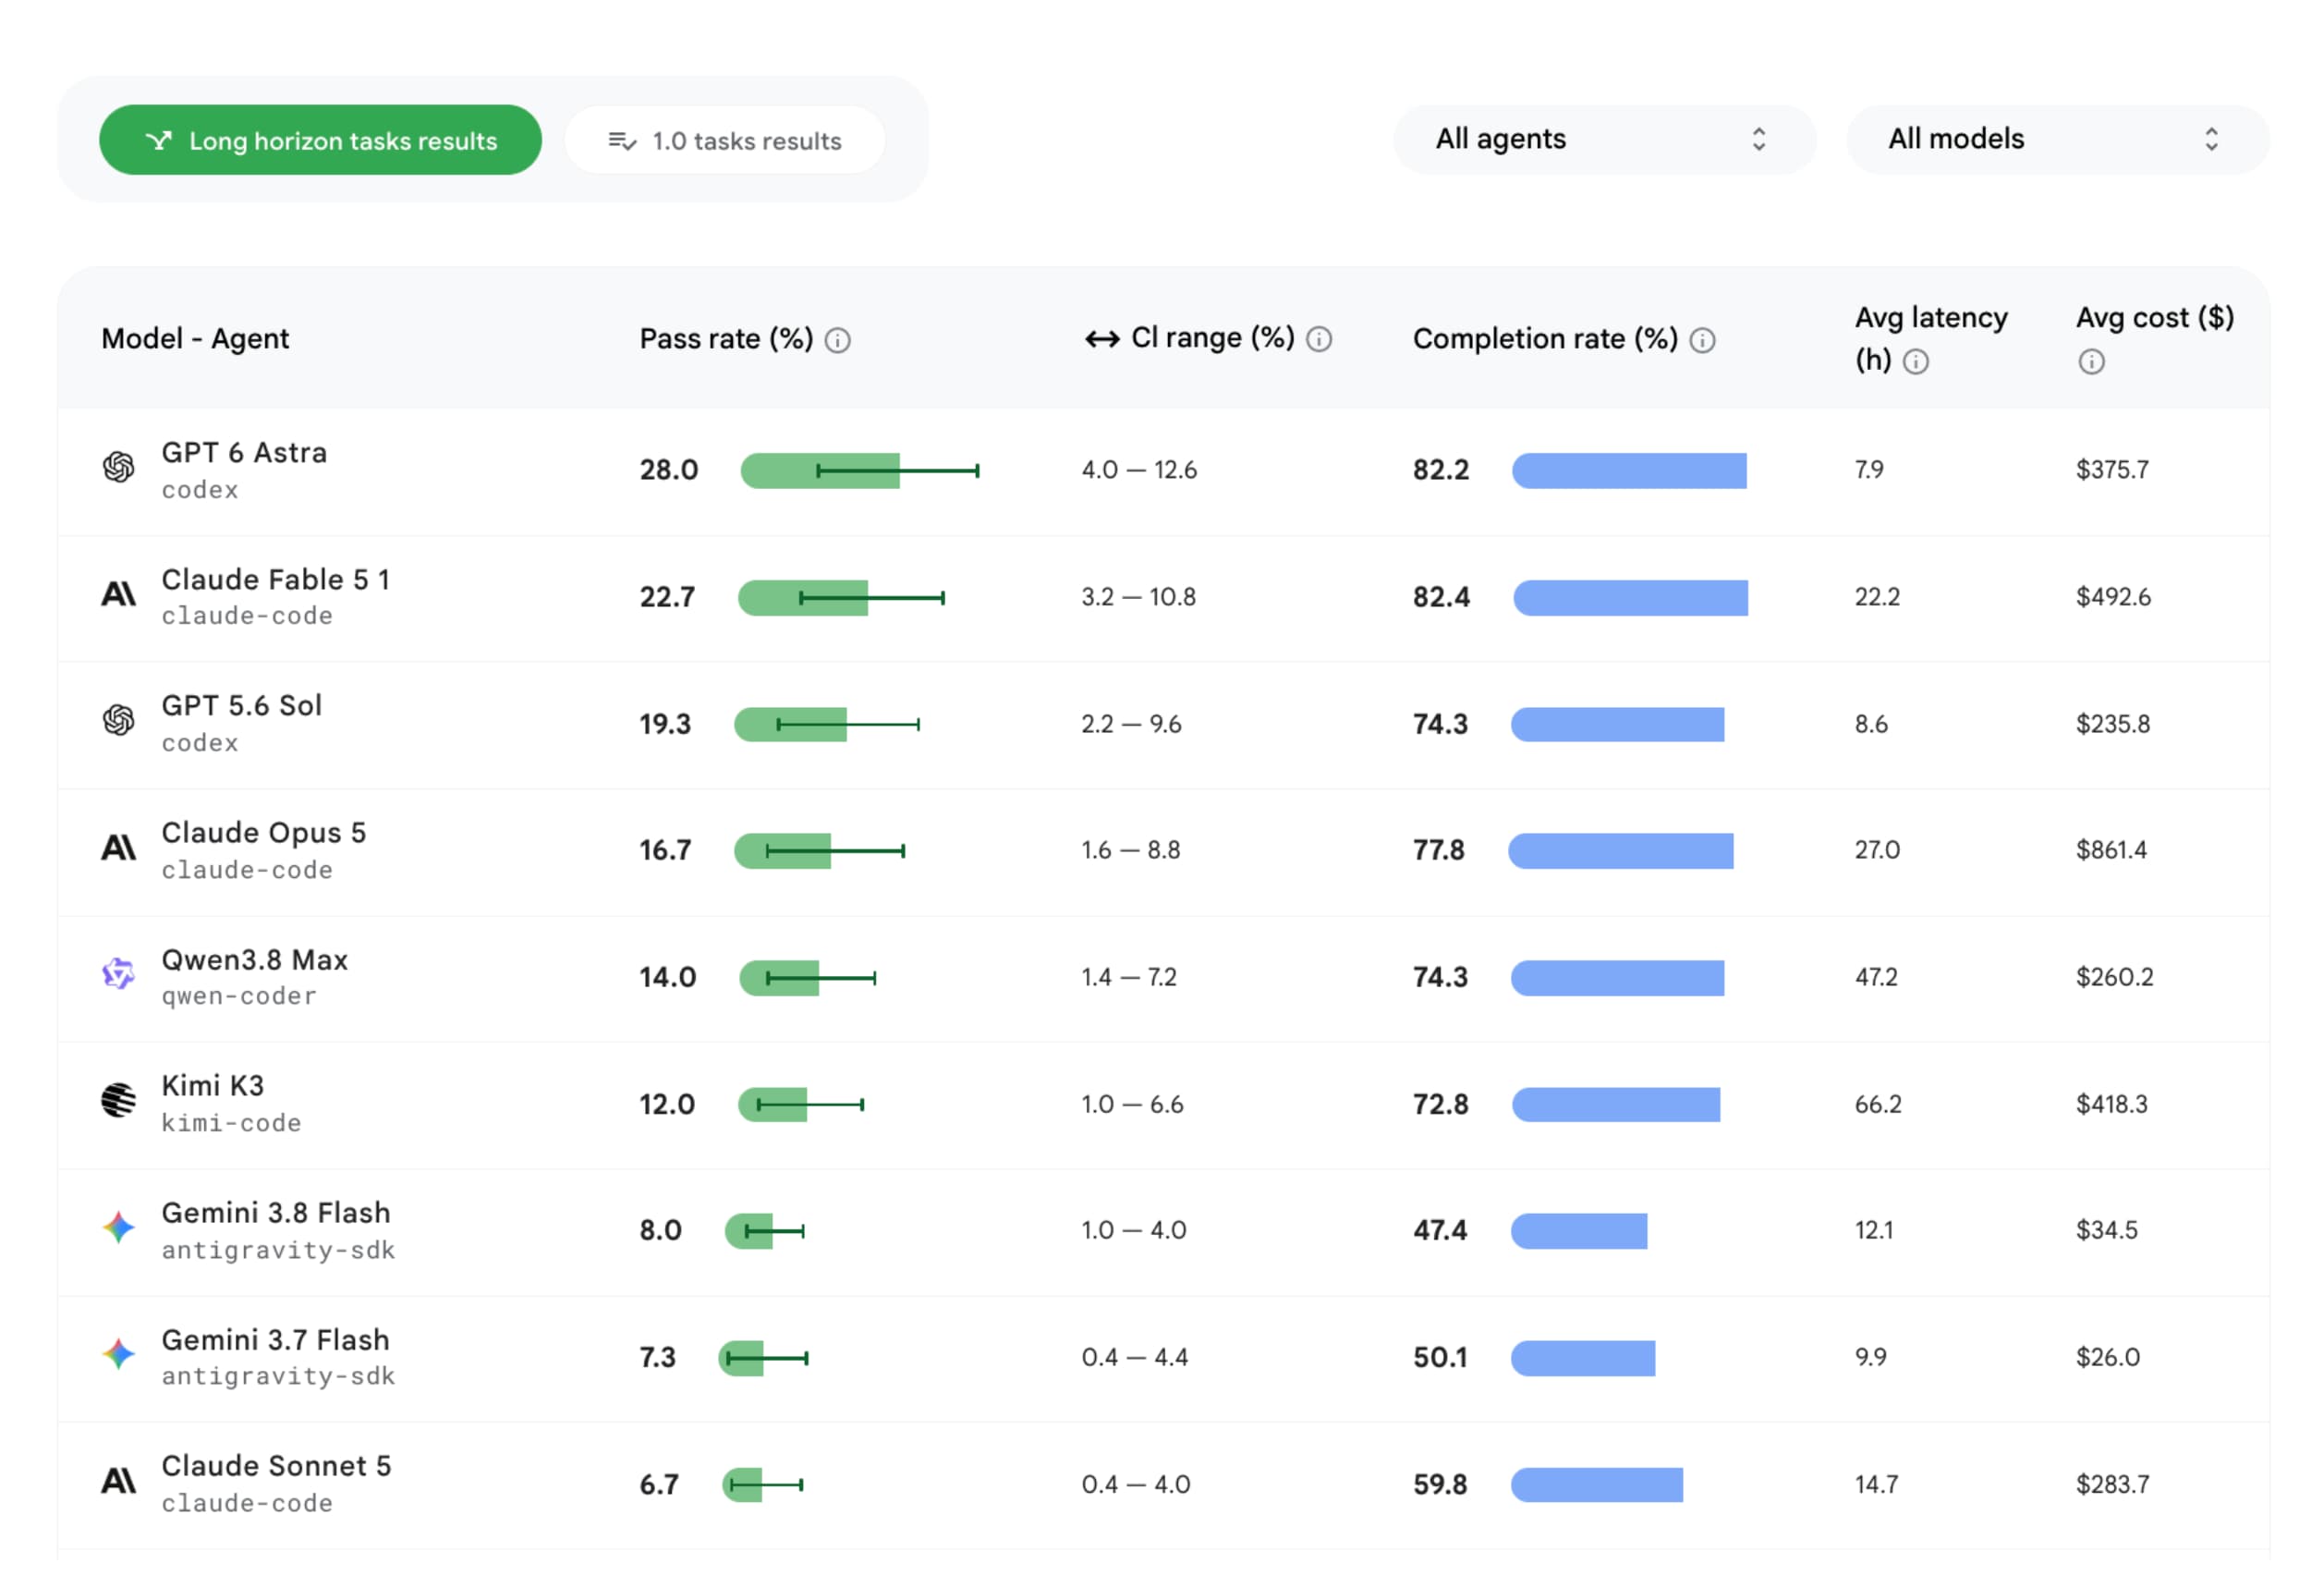
Google shared insights like how “porting cross-platform apps to Android remains an open challenge—no model hits a 100% pass rate, and frontier models reach at most a 80% completion rate.”

  • “…AI does a better job at writing new code rather than refactoring existing code. Refactors and migrations get trickier because success depends on architectural complexity rather than code volume.”
  • “Models show strong capabilities on well-established, deterministic transformations, such as converting Java to Kotlin, swapping Retrofit for Ktor, or introducing a ViewModel layer.”
  • “…models struggle when tasks require runtime validation (like missing dependency injection graphs), involve breaking framework changes, or run into knowledge gaps with unreleased libraries.”

With agent evaluations, Android Bench ran “agents from the corresponding model provider,” like Gemini 3.8 Flash on Google Antigravity and GPT-5.6 Sol with Codex. Google says “harness design positively impacts developer outcomes,” with Android Bench planning to include different model and agent combinations in the future.

Add 9to5Google as a preferred source on Google Add 9to5Google as a preferred source on Google

FTC: We use income earning auto affiliate links. More.

Схожие новости

#Наименование новостиТональностьИнформативностьДата публикации
1Google изменила критерии отбора лучших ИИ для создания приложений под Android0510-07-2026
2Android developer verification on track for September, ‘Verifier’ service will soon auto-install0518-06-2026
3Google is changing how it judges AI models for Android coding, updates list with Fable 5011.2508-07-2026
4Gemini Intelligence, Googlebook and Android 17 take center stage at Google’s Android show 2026 5713-05-2026
5Android Studio Quail 2 mit parallelen Agentenchats und LeakCanary-Integration0515-07-2026
6Google Drive’s Ask Gemini & AI Overviews come to Android with AI Pro0530-06-2026
7Google I/O 2026 Sessions List Reveals Android 17, AI, and Chrome as Key Topics for May 19 Event010.4915-04-2026
8Google on what ‘Android Halo’ does, talking less about AI, and how Gemini will use car cameras [Video]0501-07-2026
9Google Gives Families Their Own AI Agent To Manage Daily Chaos04.7620-09-2026
10Google Finance now available as dedicated Android app0525-06-2026

Классификация: . Схожих патентов: 0. Схожих новостей: 10. Тональность: 0. Информативность: 29.8. Источник: 9to5google.com.